Essential Machine Learning Skills Beginners Need to Learn
Machine learning is a core pillar of modern artificial intelligence, powering everything from recommendation engines and spam filters to complex demand forecasting and fraud detection systems. As organizations increasingly rely on data-driven decision-making, mastering machine learning skills has become a high-leverage career move for software developers, data scientists, and aspiring AI engineers.
Building proficiency in this domain requires more than passively studying algorithms or testing out standalone AI tools. To succeed, you must systematically develop machine learning skills across four key areas: writing code, analyzing data, evaluating model performance, and recognizing algorithmic limitations.
The good news is that you can build these core machine learning skills incrementally, even if you are starting from zero. You do not need to master advanced calculus or theoretical mathematics on day one; instead, success relies on consistent execution, hands-on practice, and a structured learning roadmap.
In this comprehensive guide, you will learn the foundational machine learning skills every beginner needs, the essential software and libraries to master, how to reinforce your knowledge through real-world projects, and how to position your new machine learning skills as tangible proof of professional capability.
What Is Machine Learning?
Machine learning (ML) is a core subset of artificial intelligence that shifts software development from explicit rule-writing to statistical pattern recognition. Instead of hardcoding instructions for every possible scenario, you train systems on historical data so they can independently identify patterns, make predictions, and drive automated decisions.
Consider a modern email spam filter. Instead of relying on a brittle list of manually blocked keywords, an ML model ingests thousands of labeled examples of spam and legitimate messages to uncover underlying structural patterns. It then computes the probability that a new, unseen message is malicious.
The Core Machine Learning Pipeline
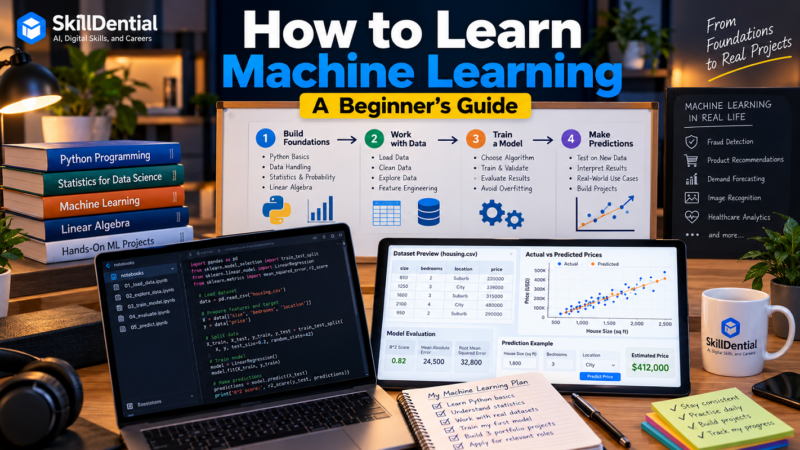
Building and deploying any ML system requires executing a systematic, six-step lifecycle:
- Data Acquisition: Collect or source high-relevance raw data.
- Data Preparation & EDA: Clean, format, handle missing values, and perform exploratory data analysis.
- Algorithm Selection: Choose the appropriate model architecture (e.g., linear regression, decision trees, neural networks) based on the problem type.
- Model Training: Feed historical data into the algorithm so it can optimize its internal parameters (weights and biases).
- Evaluation: Test model performance on an independent validation/test set to measure generalization against unseen data.
- Deployment & Monitoring: Push the model to production and continuously monitor for data drift and performance degradation.
Key Determinants of Model Performance
A model’s efficacy is bounded by four primary variables: data quality (garbage in, garbage out), algorithm suitability, rigorous evaluation methodology, and distributional alignment (how closely training data mirrors real-world production conditions).
Mastering this foundational pipeline is the prerequisite for developing high-value machine learning skills that translate into real-world engineering capability.
Python Programming
Python is the undisputed lingua franca of artificial intelligence and the primary vehicle for executing machine learning skills. Its clean syntax and massive ecosystem of data science libraries make it the optimal language for rapid experimentation, prototyping, and production deployment.
You do not need a computer science degree or years of software engineering experience before building your first model. However, you must achieve functional fluency—knowing enough Python to manipulate data structures, structure scripts, and interpret error tracebacks.
Essential Python Fundamentals for ML
Focus your initial learning curve on the core subset of Python required for data workflows:
- Data Structures: Variables, strings, lists, tuples, dictionaries, and sets for storing and organizing data.
- Control Flow: Conditional statements (
if/elif/else) and loops (for,while) for programmatic automation. - Modular Code: Writing and utilizing functions to maintain clean, reusable logic.
- File I/O: Reading and writing standard data formats (e.g., CSV, text files).
- Package Management: Importing and utilizing external modules and third-party libraries.
- Exception Handling: Reading tracebacks and debugging common runtime errors efficiently.
- Object-Oriented Basics: Understanding basic classes and object instances, which are foundational for working with modern ML frameworks like Scikit-Learn.
Practical Application & Exercise
To transition from theory to execution, you should be capable of writing scripts that ingest raw data, compute baseline metrics, and cleanly document your logic.
Practical Exercise
Write a short Python program that ingests a list of examination scores, calculates the mean, highest score, and lowest score, and prints the formatted results.
Recommended Resource: Leverage the official Python tutorial for structured syntax references, supplemented by hands-on coding environments like Jupyter Notebooks to test code interactively.
Mathematics for Machine Learning
Mathematics is the underlying engine that enables machine learning algorithms to represent real-world relationships, quantify errors, and systematically adjust their internal parameters during training.
You do not need a degree in applied mathematics before building functional models. Instead, take a just-in-time approach: start with the core mathematical concepts required to interpret datasets and tune basic models, expanding your theoretical foundation as your projects demand it.
Linear Algebra
Linear algebra provides the structural framework for handling multidimensional data. Because machine learning datasets are almost exclusively represented as numerical arrays (vectors and matrices), mathematical operations are required to transform, project, and process those values at scale.
- Core Focus Areas: Vectors, matrices, matrix dimensions, matrix multiplication, dot products, and basic vector arithmetic.
- Practical Application: A real estate dataset containing thousands of properties with columns for square footage, bedroom count, and age is natively processed by algorithms as a massive matrix of numerical features.
Probability and Statistics
Statistics gives you the tools to analyze data distribution, quantify variation, and measure model performance, while probability provides the mathematical framework for reasoning under uncertainty.
- Core Focus Areas: Mean, median, mode, variance, standard deviation, probability distributions, conditional probability, correlation, and rigorous sampling techniques.
- Practical Application: These statistical concepts help you diagnose why a model achieves high accuracy during training yet fails to generalize when exposed to unseen validation or test sets.
Basic Calculus and Optimization
Calculus is essential for understanding how parametric models learn. When an algorithm trains, it iteratively adjusts its weights to minimize a mathematical loss function.
- Core Focus Areas: Derivatives, rates of change, the definition of a gradient, and the mechanics of gradient descent.
- Practical Application: Gradient descent is the foundational optimization algorithm used to navigate a loss landscape, iteratively tweaking model parameters in the direction of steepest descent to reduce prediction error.
Practical Advice
Always study mathematical concepts alongside small Python programming exercises. Computing gradients or calculating variance programmatically bridges the gap between abstract theory and actionable machine learning skills.
Data Analysis and Data Manipulation
Data analysis is perhaps the single most critical machine learning skill you can develop, because an algorithm’s predictive power is entirely bounded by the quality and structure of the data fed into it. Before training any model, you must master the mechanics of inspecting raw datasets, auditing data hygiene, and transforming unstructured records into pristine inputs.
NumPy: High-Performance Numerical Computing
NumPy is the foundational library for numerical computing in Python, providing support for high-performance multidimensional arrays and vectorized mathematical operations.
- Core Competencies: Array creation, shape and dimension management, vector/matrix arithmetic, slicing, and fast element-wise filtering.
- Why It Matters: NumPy arrays bypass the performance bottlenecks of native Python loops, making them essential for executing the linear algebra operations required by advanced machine learning skills.
Pandas: Tabular Data Manipulation
While NumPy handles raw matrices, Pandas is the industry standard for managing heterogeneous tabular data (such as CSVs, SQL exports, and spreadsheets).
- Core Competencies: Dataset ingestion/export, indexing, multi-column filtering, record sorting, duplicate detection, grouping (
groupby), and data type coercion. - Practical Application: Imagine an enterprise analyzing user churn. You use Pandas to ingest transaction logs, flag anomalous billing records, compute rolling monthly averages, and merge customer demographic profiles into a unified training table.
Data Cleaning and Preprocessing
Raw datasets are rarely production-ready; they routinely feature missing records, structural inconsistencies, duplicate rows, and features measured across wildly different scales.
- Strategic Execution: Never blindly drop records or impute missing values with mean/median defaults. Always conduct exploratory data analysis (EDA) to uncover the root cause of anomalies before deciding whether to impute, isolate, or remove them.
- Impact: Developing a rigorous preprocessing workflow is a hallmark of professional machine learning skills that prevents data leakage and model bias.
Practical Exercise
Download a public dataset (such as from Kaggle or the UCI Machine Learning Repository), load it into a Jupyter Notebook via Pandas, audit missing values, calculate descriptive summary statistics, and document your data cleaning decisions in a markdown cell.
Data Visualisation and Exploratory Data Analysis (EDA)
Data visualisation is a foundational machine learning skill that bridges raw numerical tables and human intuition, allowing you to uncover patterns, skewness, and anomalies that summary statistics alone often miss.
Exploratory Data Analysis (EDA) is the systematic process of investigating a dataset before and during modeling to understand its underlying structure, data quality, feature distributions, and bivariate relationships.
Core Visualisation Libraries in Python
To execute effective EDA, you should master Python’s two primary plotting libraries:
- Matplotlib: The low-level plotting library that provides granular, object-oriented control over every single element of a figure (axes, labels, ticks, and layouts).
- Seaborn: Built on top of Matplotlib, Seaborn provides a high-level interface for drawing attractive, informative statistical graphics with minimal code (e.g., correlation heatmaps, pair plots, and distribution curves).
High-Value Visualisation Techniques for Beginners
Focus your early practice on mastering specific chart types designed to answer critical analytical questions:
- Histograms & Density Plots: Essential for examining feature distributions, skewness, and scaling requirements.
- Scatter Plots: Used to visualize relationships and covariance between two continuous numerical variables.
- Bar Charts: Ideal for comparing categorical frequencies or aggregated metrics across discrete groups.
- Line Charts: Crucial for tracking trends and seasonal patterns across sequential time-series data.
Avoiding Analytical Pitfalls
While visualization helps surface actionable insights, it also introduces cognitive risks. For example, plotting monthly sales might reveal a strong positive correlation between advertising expenditure and revenue. However, a visible relationship does not automatically prove causation—external factors, market trends, or confounding variables may be at play. Professional practitioners always document data limitations alongside their visual findings.
Practical Exercise
Select a public dataset, generate three distinct charts (e.g., a distribution histogram, a categorical bar chart, and a bivariate scatter plot), and write a concise technical brief explaining what each visualization reveals, including any notable outliers or data limitations.
Understanding Core Machine Learning Concepts
Before diving into advanced algorithms, you must understand how machine learning problems are structured. Mastering foundational machine learning skills requires a clear grasp of problem taxonomies, learning paradigms, and the underlying mathematical objectives of your models.
At a high level, machine learning approaches are categorized by how they process data and interact with target outcomes:
| Approach | What It Does | Common Example |
| Supervised Learning | Learns mapping functions from historical examples containing known target outcomes. | Predicting house prices based on historical sales data. |
| Unsupervised Learning | Identifies intrinsic patterns, structures, or clusters in data without supplied target labels. | Grouping customers by purchasing behavior for market segmentation. |
| Deep Learning | Utilizes multi-layer artificial neural networks to learn hierarchical representations of complex data. | Complex image classification and natural language processing. |
Note: Deep learning is a specialized subset of machine learning rather than a mutually exclusive category; deep neural networks can be trained using both supervised and unsupervised learning paradigms.
Regression (Predicting Continuous Values)
Regression models are designed to predict continuous numerical values based on input features.
- Core Applications: Estimating property valuations, forecasting inventory demand, or predicting shipping delivery times.
- Skill Focus: Begin with linear regression, learning how to interpret coefficients, compute residual errors, and evaluate predictions against actual values using metrics like Mean Squared Error (MSE).
Classification (Predicting Discrete Categories)
Classification algorithms assign observations to discrete classes or categories.
- Core Applications: Flagging emails as spam or legitimate, detecting fraudulent financial transactions, or diagnosing medical scans.
- Skill Focus: Master foundational models like logistic regression and decision trees, alongside core evaluation metrics such as accuracy, precision, recall, and the F1-score.
Clustering (Unlabeled Pattern Discovery)
Clustering algorithms group observations based on feature similarities without relying on predefined target labels.
- Core Applications: Customer segmentation, anomaly detection, and document organization.
- Skill Focus: Study K-means clustering, understanding how results depend heavily on feature scaling, initialization, and the strategic selection of the optimal number of clusters ($k$).
Practical Advice
Always start with simple, interpretable baseline models before scaling to complex architectures. Understanding a model’s underlying assumptions, computational limits, and failure modes is a hallmark of professional machine learning skills.
Feature Engineering and Data Preprocessing
Transforming raw data attributes into high-signal inputs is one of the most critical machine learning skills you can master. A feature is an individual measurable property or characteristic of the data your model uses to make predictions. However, raw data is rarely in a state where an algorithm can extract optimal value from it without deliberate engineering.
For example, a raw timestamp column containing exact transaction dates can be engineered into more predictive derived variables, such as day_of_week, hour_of_day, or is_weekend, depending on the problem domain.
Core Preprocessing Competencies for Beginners
To build robust models, focus your early skill development on these foundational preprocessing operations:
- Categorical Encoding: Converting text-based categories (e.g., product types, regions) into numerical formats using techniques like One-Hot Encoding or Label Encoding.
- Feature Scaling: Normalizing or standardizing numerical features so that variables with larger numeric ranges do not disproportionately dominate the objective function.
- Missing Value Treatment: Imputing or removing missing records based on rigorous exploratory analysis rather than arbitrary defaults.
- Feature Selection: Identifying and retaining only the features that provide true predictive power while dropping noise.
- Derived Variable Creation: Engineering domain-specific metrics that help algorithms learn underlying relationships faster.
Algorithm Sensitivity & Preprocessing
Not all models require identical preprocessing workflows. Distance-based algorithms (such as K-Nearest Neighbors and Support Vector Machines) and neural networks are highly sensitive to unscaled features. Conversely, tree-based models (such as Random Forests and Gradient Boosted Trees) are generally invariant to feature scaling, though they still require clean handling of missing values and categorical data.
The Golden Rule: Preventing Data Leakage
One of the most dangerous pitfalls for practitioners is data leakage. Leakage occurs when information from outside the training dataset—such as target labels or global statistics—accidentally influences training or evaluation, making your model appear deceptively accurate during testing.
Critical Practice
Never compute preprocessing parameters (like mean, standard deviation, or scaling factors) across your entire dataset at once. Always fit your transformers exclusively on the training subset, then apply those exact transformation parameters to your validation and test sets.
Streamlining Workflows with Scikit-Learn Pipelines
To automate preprocessing safely and eliminate human error, master Scikit-learn Pipelines. Pipelines allow you to chain data transformers and estimators into a single reproducible workflow, ensuring your data cleaning, scaling, and modeling steps are executed in the correct sequence without risking data leakage.
Model Training, Evaluation, and Validation
Training a model is only the midpoint of a machine learning workflow. The true test of your machine learning skills lies in your ability to rigorously evaluate whether a model’s predictions are reliable, stable, and generalizable to unseen real-world data.
Train, Validate, and Test Splits
To prevent self-deception during development, you must partition your data into distinct subsets before modeling begins:
- Training Set: Used exclusively to fit the model and optimize internal parameters.
- Validation Set: Used iteratively to compare architectures, tune hyperparameters, and select the best-performing approach.
- Test Set: Kept entirely isolated until the very end for an unbiased, final assessment of the model’s true generalization ability.
Alternative Workflow: For smaller datasets, practitioners often use cross-validation (such as $k$-fold cross-validation) to rotate training and validation splits systematically, ensuring robust performance estimates without wasting scarce data.
The Golden Rule
Never evaluate or adjust your model iteratively against your test set. Doing so causes data leakage into the evaluation phase, resulting in overly optimistic performance metrics that will collapse in production.
Choosing the Right Evaluation Metrics
Different problem domains require distinct mathematical metrics to accurately reflect real-world performance. Relying on a single default score can mask critical failures:
| Metric | Problem Type | What It Measures | Critical Limitation / Consideration |
| Mean Absolute Error (MAE) | Regression | The average magnitude of prediction errors in absolute terms. | Does not heavily penalize large, catastrophic errors. |
| Root Mean Squared Error (RMSE) | Regression | The square root of the average squared differences between predicted and actual values. | Disproportionately penalizes larger errors due to squaring. |
| Accuracy | Classification | The total percentage of correct predictions out of all predictions made. | Highly misleading when dealing with imbalanced datasets. |
| Precision | Classification | Of all predicted positives, how many were actually positive (minimizes false positives). | Ignores false negatives entirely. |
| Recall | Classification | Of all actual positives, how many did the model successfully identify (minimizes false negatives). | Ignores false positives entirely. |
| F1 Score | Classification | The harmonic mean of precision and recall. | Balances trade-offs, but can obscure performance if one metric is near zero. |
Real-World Example
A credit card fraud detection model boasting 99% accuracy can be completely useless if 99% of transactions in the dataset are legitimate. If the model simply predicts “not fraud” every time, it achieves 99% accuracy while missing 100% of actual fraud. Selecting precision, recall, or the F1 score based on actual business consequences is a core machine learning skill.
Diagnosing Overfitting and Underfitting
When evaluating models, you must monitor the gap between training and validation performance to detect two common failure modes:
- Overfitting: The model learns the training data too well, capturing random noise and idiosyncratic patterns rather than true underlying relationships. It achieves near-perfect training scores but fails miserably on validation and test data.
- Underfitting: The model is overly simplistic, restricted, or insufficiently trained to capture the essential patterns in the data, resulting in poor performance across both training and validation sets.
Remediation
You can diagnose and mitigate these issues by comparing training versus validation curves, simplifying overly complex models, applying regularization techniques, expanding dataset size, or refining your feature engineering pipeline.
Problem-Solving and Critical Thinking
Executing code and tuning hyperparameters are only half the battle. One of the most underrated machine learning skills is the ability to think critically about problem framing—determining whether a business or operational challenge is actually suited for machine learning in the first place, defining what success looks like, and selecting the simplest architecture that gets the job done.
Technical brilliance cannot salvage a model that solves the wrong problem.
The 7-Part Problem-Framing Framework
Before writing a single line of training code, professional practitioners interrogate the problem using a structured framework:
- Problem Definition: What specific real-world problem needs to be solved?
- Decision Support: What operational decision or workflow will the model’s output directly support?
- Data Audit: What data is currently available, and how reliable, complete, and unbiased is it?
- Target Definition: What exact outcome or label should the model predict?
- Baseline Establishment: What simple heuristic, rule-based approach, or baseline model must be built first for comparison?
- Error Cost Analysis: Which classification or regression errors (false positives vs. false negatives) carry the highest financial or operational cost?
- Evaluation Criteria: How will success be measured against real-world constraints?
Case Study: Retail Demand Forecasting
Imagine an enterprise wanting to optimize inventory using machine learning. Before choosing between a complex Long Short-Term Memory (LSTM) neural network or a gradient-boosted tree, you must define the forecasting horizon, map historical stockouts and promotional spikes, account for seasonal anomalies, and calculate whether a 5% forecasting error costs more in holding inventory or lost sales.
The Principle of Parsimony: Simplicity Over Complexity
Beginners often make the mistake of deploying overly complex models when a simpler approach would suffice.
- The Baseline Rule: Always start with a transparent, easily interpretable baseline (such as a moving average or logistic regression).
- The Trade-off: Simple models are cheaper to maintain, easier to debug, more transparent for stakeholders, and frequently competitive with complex architectures.
Cultivating this strategic judgment is a defining machine learning skills milestone that separates hobbyists from professional AI engineers.
Machine Learning Tools and Libraries
You do not need to master every framework, library, and tool in the ecosystem on day one. To build practical machine learning skills, you only need a lean, cohesive stack that supports the entire end-to-end workflow—from data ingestion to model deployment.
The Essential Machine Learning Toolchain
| Tool / Library | Primary Purpose | When to Learn It |
| Python | Programming foundation and workflow automation. | First (Day one of coding). |
| NumPy | High-performance numerical computing and array operations. | Early (Immediately after basic Python syntax). |
| Pandas | Tabular data manipulation, cleaning, and transformation. | Early (Alongside basic data structures). |
| Matplotlib & Seaborn | Exploratory data visualization and statistical plotting. | Alongside data analysis. |
| Jupyter Notebooks | Interactive coding, rapid prototyping, and experiment documentation. | Early (Your primary learning environment). |
| Scikit-Learn | Classical machine learning algorithms, data preprocessing, and evaluation. | After mastering basic data analysis. |
| Git & GitHub | Version control, experiment tracking, and portfolio sharing. | As projects grow beyond single scripts. |
| PyTorch or TensorFlow | Deep learning, neural networks, and advanced architectures. | After securing core machine learning fundamentals. |
Recommended Learning Sequence
- The Data Foundation: Start with Python, Jupyter Notebooks, NumPy, and Pandas. You cannot build effective models if you cannot clean and manipulate your data.
- The Modeling Core: Move directly to Scikit-Learn. It is the industry standard for classical machine learning, providing unified APIs for everything from linear regression to random forests, along with built-in preprocessing and cross-validation utilities.
- The Deep Learning Frontier: Defer frameworks like PyTorch or TensorFlow until you have a firm grasp of core machine learning principles. Neural networks compound your understanding, but classical models teach you the fundamental mechanics of training, evaluation, and overfitting first.
Official Resources
Leverage the official documentation and getting-started guides provided by the maintainers—specifically the Scikit-learn Getting Started Guide, PyTorch Beginner Tutorials, and TensorFlow Core Guides—rather than relying on fragmented third-party tutorials.
Basic SQL and Data Handling
While you can start your machine learning journey using pre-formatted CSV files, real-world data almost always lives in relational databases. Mastering basic Structured Query Language (SQL) is a high-leverage machine learning skill that allows you to extract, filter, and aggregate raw data directly from the source before bringing it into Python for modeling.
Core SQL Competencies for Practitioners
You do not need to become a database administrator, but you must be able to query relational databases efficiently:
- Data Retrieval & Filtering: Using
SELECT,WHERE, sorting (ORDER BY), and limiting (LIMIT) to pull targeted subsets of data. - Aggregation: Using
GROUP BYalongside aggregate functions (COUNT,SUM,AVG,MAX,MIN) to summarize enterprise data at scale. - Relational Joins: Executing
INNER JOINandLEFT JOINoperations to merge disparate data sources—such as linking customer demographic tables with behavioral transaction logs. - Data Hygiene: Handling
NULLvalues and filtering precise date ranges to prevent temporal leakage at the query level.
The SQL-to-Python Pipeline
In a professional environment, your workflow typically starts in SQL—extracting enterprise data, filtering out noise, and computing initial aggregations—before exporting the dataset into Python and Pandas for exploratory data analysis and feature engineering.
Data Ethics, Provenance, and Privacy
Developing professional machine learning skills extends beyond technical execution into data governance and ethics. Before building or publishing any model, you must ensure compliance across three critical fronts:
- Data Provenance: Accurately document where your datasets originated, how they were collected, and any known limitations.
- Usage Rights: Verify that you have legal or contractual permission to use the data for your intended modeling purpose.
- Data Privacy & Redaction: Never expose Personally Identifiable Information (PII), confidential financial records, or proprietary credentials in public portfolios or open-source repositories like GitHub. Sanitize and anonymize your inputs rigorously.
Communication, Interpretation, and Responsible AI
A technically accurate model is useless if its stakeholders cannot understand it, trust it, or safely deploy it. Developing elite machine learning skills requires mastering more than just mathematics and coding; you must also become proficient in translating complex statistical outputs into actionable, transparent, and ethically sound business insights.
A high-performing model built on flawed assumptions or opaque logic can introduce severe operational, financial, and ethical risks—especially when deployed in high-stakes domains like hiring, healthcare, finance, or public services.
Core Competencies for Responsible AI Practice
To bridge the gap between raw code and real-world impact, focus on mastering these non-technical communication and governance competencies:
- Plain-Language Translation: Translate complex metrics (such as ROC-AUC, precision-recall trade-offs, and feature importances) into clear, accessible language for executive stakeholders and non-technical decision-makers.
- Rigorous Documentation: Document every assumption, data transformation, known failure mode, and limitation directly alongside your code and model cards.
- Bias and Fairness Auditing: Actively interrogate your datasets and model outputs for historical bias, systemic skew, and demographic disparities. Algorithms trained on biased data will automate and amplify that bias at scale.
- Quantifying Uncertainty: Never present probabilistic predictions as absolute certainties. Clearly communicate confidence intervals and edge cases.
- Human-in-the-Loop Governance: Define clear operational boundaries for when an automated system must defer to human review, particularly for high-consequence decisions involving people’s livelihoods or capital.
Applied Example: Customer Churn Reporting
Imagine you have trained a model that flags customers likely to cancel their subscription. A professional report leveraging your machine learning skills would not simply dump a list of names or claim 95% accuracy. Instead, it would:
- Explain the evaluation metrics used (e.g., optimizing recall to catch as many at-risk accounts as possible).
- Highlight key predictive drivers (e.g., sudden drops in platform logins).
- Explicitly state limitations (e.g., the model cannot predict external macro events or sudden competitor pricing changes).
- Outline a responsible intervention strategy that combines automated alerts with human customer success outreach.
The Professional Standard
True mastery of machine learning skills is measured not just by how well your model minimizes loss on a test set, but by how responsibly, transparently, and effectively its insights drive real-world decisions.
Practical Machine Learning Projects
Theory alone is insufficient; practical projects are the ultimate vehicle for turning abstract knowledge into demonstrable machine learning skills. A well-executed portfolio project proves that you can ingest raw data, engineer features, train and tune models, evaluate results rigorously, and articulate your decisions to stakeholders.
Beginners should start with small, well-defined problems before attempting complex deep learning architectures.
House Price Prediction (Regression)
- Goal: Predict a property’s market price using numerical and categorical features.
- Core Machine Learning Skills Demonstrated: Python/Pandas data manipulation, exploratory data analysis, regression modeling, RMSE/MAE evaluation, and prediction error interpretation.
- Best Practice: Use a publicly available dataset with a clear license (e.g., Boston Housing alternative or Ames Housing dataset). Always document that estimated prices are statistical estimates, not guaranteed market valuations.
Spam Message Classification (Supervised Classification)
- Goal: Classify incoming text messages as spam or legitimate.
- Core Machine Learning Skills Demonstrated: Text preprocessing, feature extraction (TF-IDF/Vectorization), classification algorithms, precision-recall-F1 evaluation, and error analysis.
- Best Practice: Discuss the operational risk of false positives (misclassifying a legitimate message as spam) and explain why raw accuracy is a misleading metric for imbalanced text datasets.
Customer Segmentation (Unsupervised Clustering)
- Goal: Group customers with similar purchasing behaviors and characteristics.
- Core Machine Learning Skills Demonstrated: Exploratory data analysis, feature scaling, K-means clustering, cluster visualization, and cluster profiling.
- Best Practice: Emphasize that discovered clusters are analytical groupings designed for targeted marketing, not immutable or permanent customer types.
Student Performance Analysis (Descriptive & Predictive Modeling)
- Goal: Explore whether study habits and demographic factors correlate with academic outcomes.
- Core Machine Learning Skills Demonstrated: Data cleaning, descriptive statistics, visualization, regression/classification modeling, and responsible interpretation.
- Best Practice: Strictly avoid treating statistical correlations as absolute proof of causation, and never use the model to make high-stakes, unappealable judgments about individual students.
What Every Project Report Must Include
To showcase true mastery of machine learning skills, publish your projects with a professional, comprehensive project report containing:
- Problem Statement: The real-world problem and its intended operational use.
- Data Provenance: The dataset source, collection method, and licensing terms.
- Exploratory Analysis: Data preparation steps, cleaning decisions, and EDA visualizations.
- Architecture Selection: The chosen model and a clear justification for why it was selected.
- Evaluation Strategy: The validation approach and metrics used to measure success.
- Results & Error Analysis: A breakdown of performance, residual errors, and failure modes.
- Reproducibility Guide: Clear instructions, requirements files, and code to run the project.
- Future Improvements: Concrete ideas for feature expansion or architectural refinement.
The Portfolio Rule
A single well-documented, original project that you can explain line-by-line is exponentially more valuable than a GitHub repository filled with copied, ununderstood notebooks.
A Beginner’s Roadmap for Learning Machine Learning Skills
The 12-week plan below provides a structured, phased approach to mastering foundational machine learning skills. This is an illustrative timeline rather than a rigid rule; your actual pace will depend on your prior programming background, available study hours, and project complexity.
| Timeframe | Learning Focus | Practical Milestone |
| Weeks 1–2 | Python Fundamentals | Write modular scripts, handle data structures, and debug errors. |
| Weeks 3–4 | NumPy, Pandas, & Visualisation | Ingest, clean, and perform EDA on a raw dataset. |
| Weeks 5 | Probability, Statistics, & Core Math | Compute descriptive stats and interpret feature relationships. |
| Weeks 6–7 | Supervised Learning & Algorithms | Build and train baseline regression and classification models. |
| Weeks 8 | Unsupervised Learning & Clustering | Apply K-means to discover patterns and segments in unlabeled data. |
| Weeks 9 | Evaluation, Validation, & Leakage | Build robust pipelines and evaluate models using domain-specific metrics. |
| Weeks 10–11 | End-to-End Project Execution | Build, document, and publish a complete portfolio project. |
| Weeks 12 | Portfolio & Technical Communication | Publish code to GitHub, write a clear project report, and articulate findings. |
Adapting Your Timeline
- If you are new to programming: Allocate additional time to Weeks 1–4 to build fluent Python and Pandas mechanics before touching modeling algorithms.
- If you have existing data experience: You can compress the early data analysis phases and accelerate directly into Scikit-Learn modeling and pipeline architecture.
Final Takeaway
Mastering machine learning skills is a marathon of deliberate practice, systematic problem-solving, and continuous experimentation. By focusing on fundamentals—clean data, rigorous evaluation, simple baseline models, and clear communication—you build a durable foundation that scales alongside your career in AI and technology.
Free Resources to Begin Learning
Accelerating your mastery of machine learning skills does not require expensive bootcamps or specialized credentials. Many of the industry’s highest-quality educational materials are available for free directly from leading technology organizations, open-source maintainers, and core library developers.
Review the curated list of official resources below to support your practical learning roadmap:
- Google Machine Learning Crash Course
- What it covers: Core concepts including regression, classification, data preprocessing, and model evaluation through interactive visual explanations and coding exercises.
- When to use: Once you have acquired basic Python programming and foundational mathematical literacy.
- Official Python Tutorial
- What it covers: Programming fundamentals, syntax, control flow, functions, and data structures.
- Best practice: Do not just read the documentation; actively write code alongside the tutorial and complete the accompanying exercises.
- NumPy and Pandas Documentation
- What it covers: The NumPy quickstart guide and Pandas getting-started tutorials for high-performance array operations and tabular data manipulation.
- When to use: Immediately after securing basic Python syntax.
- Scikit-Learn Getting-Started Guide
- What it covers: Classical machine learning algorithms, data preprocessing utilities, pipeline construction, and rigorous evaluation metrics.
- When to use: When you are ready to build, tune, and evaluate your first predictive models.
- PyTorch or TensorFlow Beginner Tutorials
- What it covers: Artificial neural networks, deep learning architectures, and tensor operations.
- Best practice: Defer this stage until you have established a firm grasp of classical machine learning skills and data fundamentals.
Operational Note
Course availability, interface layouts, and external curricula change frequently. Always verify each provider’s current terms, documentation updates, and repository releases as you progress through your learning journey.
Common Mistakes Beginners Should Avoid
Accelerating your acquisition of machine learning skills requires not only knowing what to do, but actively avoiding the systemic pitfalls that derail beginner progress. Avoiding these common traps will save you time and build deeper technical competence.
Trying to Learn Everything at Once
- The Pitfall: Attempting to simultaneously master Python, advanced multivariable calculus, SQL, cloud infrastructure, deep learning frameworks, and MLOps on day one leads directly to cognitive overload and burnout.
- The Better Approach: Follow a disciplined, sequential learning roadmap. Master the fundamentals first, build small projects to reinforce each phase, and layer on advanced subjects only when your current workflow demands them.
Memorizing Algorithms Without Understanding the Problem
- The Pitfall: Collecting algorithm names (e.g., Random Forests, XGBoost, Neural Networks) without understanding their underlying assumptions or proper use cases.
- The Better Approach: Always start by defining the prediction task, interrogating the data distribution, establishing a simple baseline model, and systematically selecting algorithms that fit the problem structure.
Ignoring Data Quality
- The Pitfall: Feeding raw, uninspected data directly into an algorithm while ignoring missing values, structural duplicates, inconsistent labels, and noisy targets.
- The Better Approach: Treat Exploratory Data Analysis (EDA) and data hygiene as non-negotiable prerequisites. Audit your datasets thoroughly and document every cleaning decision.
Evaluating a Model on Training Data Alone
- The Pitfall: Measuring success using training accuracy. A model can easily memorize training data (including random noise) and achieve a 100% score while failing on unseen data.
- The Better Approach: Always partition your data using an appropriate cross-validation or train-test split strategy, reserving your test set exclusively for a final, honest evaluation.
Ignoring Data Leakage
- The Pitfall: Accidentally allowing target information or global scaling parameters from the validation/test sets to leak into the training phase.
- The Better Approach: Maintain strict data separation, fit all feature transformers and scalers exclusively on the training subset, and leverage automated pipelines (like Scikit-Learn Pipelines) to enforce structural safety.
Treating a High Score as Proof of Real-World Utility
- The Pitfall: Assuming that a high evaluation metric (like 99% accuracy) guarantees operational success, ignoring shifting real-world conditions or asymmetric error costs.
- The Better Approach: Perform deep error analysis, compare your model against simple baseline heuristics, evaluate the real-world consequences of false positives vs. false negatives, and establish continuous monitoring for deployed systems.
Copying Projects Without Understanding Them
- The Pitfall: Downloading a GitHub notebook, running the cells, and assuming you have acquired the underlying machine learning skills. Copied code provides zero evidence of independent problem-solving.
- The Better Approach: Use tutorials as a learning scaffold, but always modify the project—swap out the dataset, test an alternative algorithm, rewrite the code line-by-line, and document your findings in your own words.
Which Machine Learning Skills Should You Learn First?
If you are overwhelmed by the breadth of the AI ecosystem, prioritize the foundational machine learning skills that unlock subsequent stages of technical development. Follow this logical sequence to minimize cognitive overload:
- Python Fundamentals: Acquire enough programming fluency to write clean scripts, use control flow, manage data structures, and debug errors.
- Data Handling & Manipulation: Master Pandas and NumPy to ingest, inspect, clean, and transform raw datasets into structured arrays.
- Statistics & Visualisation: Understand distributions, central tendencies, bivariate relationships, and uncertainty using Matplotlib and Seaborn.
- Core ML Concepts: Learn how to formulate supervised (regression, classification) and unsupervised (clustering) problems.
- Model Evaluation & Validation: Master train-test separation, cross-validation, domain-specific evaluation metrics, and the mechanics of preventing data leakage.
- Practical Project Execution: Apply the end-to-end workflow to solve well-defined, real-world problems with transparent objectives.
- Specialisation: Expand into advanced domains—such as deep learning, natural language processing, or computer vision—only after your classical foundations are secure.
Note: This sequence is a pragmatic guide, not an immutable law. Adapt the roadmap to leverage your existing strengths in programming, mathematics, or data analysis.
Career Opportunities That Use Machine Learning Skills
Developing professional machine learning skills opens doors across a diverse spectrum of technical and data-centric roles in modern organizations. However, the specific depth of technical expertise required varies significantly by role and employer.
| Career Path | Core Competencies & Relevant Skills | Primary Focus |
| Data Analyst | SQL, Python, data cleaning, descriptive statistics, visualization. | Auditing business performance, reporting insights, and preparing foundational data. |
| Data Scientist | Statistical modeling, experimental design, machine learning algorithms, cross-functional communication. | Extracting predictive insights, testing hypotheses, and solving complex business problems. |
| Machine Learning Engineer | Software engineering, ML pipelines, automated testing, version control, model deployment. | Scaling experimental models into robust, production-ready enterprise systems. |
| AI Engineer | Machine learning fundamentals, AI frameworks, rapid application development, system evaluation. | Integrating pre-built or custom AI models into functional software products and user workflows. |
| Research-Oriented ML Specialist | Advanced mathematics, theoretical modeling, custom architecture design, rigorous experimental methods. | Advancing state-of-the-art algorithms and developing novel deep learning architectures. |
Navigating the Career Landscape
While these roles frequently overlap in startup environments or smaller teams, they are not interchangeable. For instance, an entry-level data analyst position focuses heavily on SQL querying and dashboard reporting, whereas a machine learning engineering role demands rigorous software engineering, pipeline automation, and production deployment capabilities.
Strategic Note
Completing a beginner course or tutorial does not automatically qualify you for senior engineering positions. Use your learning roadmap to identify individual skill gaps, analyze target job descriptions in your preferred market, and build original portfolio projects that provide undeniable, verifiable proof of your technical abilities.
Can I learn machine learning without a computer science degree?
Yes. You can build functional competence and start your career through high-quality documentation, open-source resources, online guides, and portfolio projects without a computer science degree. However, certain enterprise employers or specialized roles may require a relevant degree or equivalent professional experience, and senior research positions often demand advanced mathematical and software engineering knowledge.
Do I need to be a math prodigy to learn machine learning?
No. While mathematics is foundational to understanding algorithms, you do not need a math degree to start. Begin with basic statistics, probability, and linear algebra while developing your Python programming skills. You can layer on more advanced calculus and optimization techniques gradually as you tackle more complex architectures.
Is Python strictly necessary for machine learning?
Python is the dominant industry standard, but it is not the only language. While other languages (such as R, C++, or Julia) are used in specific research or high-performance production environments, Python remains the most practical starting point for beginners due to its massive data science ecosystem, readable syntax, and extensive libraries like Scikit-Learn, Pandas, and NumPy.
How long does it take to learn machine learning?
There is no single universal timeline. Your progress depends heavily on your prior programming background, daily study hours, and project complexity. A structured 12-week roadmap can establish a solid foundation, but developing true professional capability requires ongoing practice, continuous iteration, and multiple end-to-end portfolio projects.
Can I learn machine learning entirely for free?
Yes. You can acquire world-class foundational knowledge using free official documentation, educational materials, public datasets, and introductory guides provided by Google, Python, NumPy, Pandas, and Scikit-Learn. While some specialized bootcamps, university certificates, or cloud compute providers charge for premium features, the core knowledge costs nothing.
Which machine learning project should a beginner build first?
Start with a small, well-defined problem featuring a clean, understandable dataset. A basic house-price regression task or a text-based spam classification project will allow you to practice end-to-end data preparation, model training, evaluation, and reporting without getting bogged down by unnecessary complexity. Choose a topic that aligns with your specific career interests.
What is the difference between machine learning and deep learning?
Deep learning is a specialized subset of machine learning. While machine learning encompasses a wide range of algorithms that learn patterns from data (including linear models, decision trees, and support vector machines), deep learning specifically utilizes multi-layer artificial neural networks. Deep learning powers advanced applications like computer vision and large language models, but it is not required—or even optimal—for every machine learning problem.
In Conclusion
Mastering the essential machine learning skills—ranging from Python programming and data manipulation to exploratory visualization, rigorous model evaluation, and clear technical communication—is a journey of deliberate, incremental progress.
You do not need to memorize every advanced algorithm or master multivariate calculus before building your first functional model. True competence is built through a practical, iterative sequence:
- Establish your programming foundation with Python, NumPy, and Pandas.
- Grasp core statistical principles and data visualization techniques.
- Learn foundational supervised and unsupervised algorithms using Scikit-Learn.
- Practice rigorous validation, error analysis, and metric selection.
- Consolidate your knowledge by building and documenting an end-to-end portfolio project.
Your Immediate Next Step
Choose one beginner-friendly dataset from a public repository like Kaggle or the UCI Machine Learning Repository, load it into a Jupyter Notebook using Python and Pandas, and write down three specific questions you want your exploratory analysis to answer.
Taking that single, concrete action gives you an immediate, practical starting point for building real-world machine learning skills and turning theory into tangible execution.